Saturday, 18 April 2020

3d fashion dataset

Deep Fashion3D: A Dataset and Benchmark for 3D Garment Reconstruction from Single Images


We present Deep Fashion3D, a large-scale repository of 3D clothing models reconstructed from real garments. It contains over 2000 3D garment models, spanning 10 different cloth categories. Each model is richly labeld with groundtruth point cloud, multi-view real images, 3D body pose and a novel annotation named feature lines. With Deep Fashion3D, inferring the garment geometry from a single image becomes possible.


official :


A Multi-view Multi-source Benchmark for Drone-based Geo-localization


github:

MoVi: A Large Multipurpose Motion and Video Dataset


https://www.biomotionlab.ca/movi/

SPARE3D

A Dataset for SPAtial REasoning on Three-View Line Drawings


official site:

github:

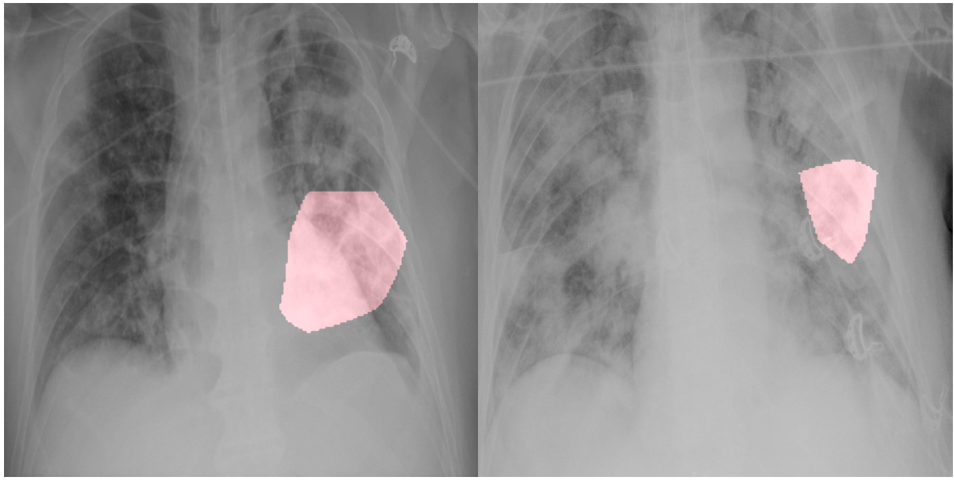
COVIDx


COVID-Net Open Source Initiative


Friday, 17 April 2020

Dataset Finders

Dataset Finders

Government & Statistics Data

Government & Statistics Data

Health & Biology Data

Health & Biology Data

Miscellaneous Datasets

Miscellaneous Datasets

Symbolic Music Datasets

Symbolic Music Datasets

Speech Datasets

Speech Datasets
  • 2000 HUB5 English: English-only speech data used most recently in the Deep Speech paper from Baidu.
  • LibriSpeech: Audio books data set of text and speech. Nearly 500 hours of clean speech of various audio books read by multiple speakers, organized by chapters of the book containing both the text and the speech.
  • VoxForge: Clean speech dataset of accented english. Useful for instances in which you expect to need robustness to different accents or intonations.
  • TIMIT: English-only speech recognition dataset.
  • CHIME: Noisy speech recognition challenge dataset. Dataset contains real simulated and clean voice recordings. Real being actual recordings of 4 speakers in nearly 9000 recordings over 4 noisy locations, simulated is generated by combining multiple environments over speech utterances and clean being non-noisy recordings.
  • TED-LIUM: Audio transcription of TED talks. 1495 TED talks audio recordings along with full text transcriptions of those recordings.

Networks and Graphs

Networks and Graphs
  • Amazon Co-Purchasing: Amazon Reviews crawled data from “the users who bought this also bought…” section of Amazon, as well as Amazon review data for related products. Good for experimenting with recommendation systems in networks.
  • Friendster Social Network Dataset: Before their pivot as a gaming website, Friendster released anonymized data in the form of friends lists for 103,750,348 users.

Recommendation and ranking systems

Recommendation and ranking systems
  • Movielens: Movie ratings dataset from the Movielens website, in various sizes ranging from demo to mid-size.
  • Million Song Dataset: Large, metadata-rich, open source dataset on Kaggle that can be good for people experimenting with hybrid recommendation systems.
  • Last.fm: Music recommendation dataset with access to underlying social network and other metadata that can be useful for hybrid systems.
  • Book-Crossing dataset:: From the Book-Crossing community. Contains 278,858 users providing 1,149,780 ratings about 271,379 books.
  • Jester: 4.1 million continuous ratings (-10.00 to +10.00) of 100 jokes from 73,421 users.
  • Netflix Prize:: Netflix released an anonymized version of their movie rating dataset; it consists of 100 million ratings, done by 480,000 users who have rated between 1 and all of the 17,770 movies. First major Kaggle style data challenge. Only available unofficially, as privacy issues arose.

Sentiment

Sentiment
  • Multidomain sentiment analysis dataset An older, academic dataset.
  • IMDB: An older, relatively small dataset for binary sentiment classification. Fallen out of favor for benchmarks in the literature in lieu of larger datasets.
  • Stanford Sentiment Treebank: Standard sentiment dataset with fine-grained sentiment annotations at every node of each sentence’s parse tree.

Popular Posts